



Proven to Optimized is a short blog series drawn from lived experience on both sides of the implementation table. After more than two decades working within a utility, I’ve seen how early, well-intentioned market decisions tend to persist long after their original context has changed.
Now working from the vendor side with many utilities at once, I see those same patterns repeat. Markets+ creates a rare pause point before designs, workflows, and integrations get locked in again.
This series explores that moment — what tends to stick, why it does, and how experience can be used before go‑live to move from what’s proven to what’s truly optimized.
In this final post, I want to move past finding the friction and focus on what to do about it: how to use the last responsible moment before go-live, instead of watching it pass by default.
Part 3 of this series (“How to Audit a Workflow That Isn’t Broken”) ended with a tease about moving from finding the friction to acting on it, and I’ll admit that’s an easier line to write than to actually do. Knowing a workflow has outlived the reason it was built doesn’t tell you what to do about it, or more importantly, when you’re still allowed to do anything about it.
That’s really the tension this whole series keeps circling back to: less what to change, more when changing it is still on the table.
There’s a phrase from lean product development I keep coming back to: the last responsible moment. The idea is you can delay a decision right up until delaying it starts costing more than deciding would. Call that stretch “the window.” Push past it and the decision still gets made, just not by anyone in particular. It gets made by whoever built the workaround first, or by whatever the tool defaulted to, or by nobody at all.
Usually that’s not for lack of awareness. Changing course when a market already feels unfamiliar seems riskier than sticking with what’s proven, whichever side of the table you’re on, and I’ve felt that pull myself. Vendors aren’t exempt either, and neither side fixes it alone: A design or a piece of code that worked for one market doesn’t automatically belong in the next one just because it’s been proven somewhere else, and a client auditing their own workflows while the vendor quietly ships that same old pattern into the build just moves the blind spot across the table. The fix is asking the question out loud, in the same room, instead of each side assuming the other one already checked.
That’s easier to say than to actually build into a project, though, so it helps to know exactly where that asking is supposed to happen. For a market implementation, that moment has a calendar attached to it. Requirements gathering. Design. Implementation stories. Testing and pre-market trials. Once the system is live, the workflow just becomes how things are done, and Parts 1 and 2 (“Why Early Market Decisions Are So Hard to Undo” and “How Proven Decisions Become Technical Debt”) covered what happens from there: Decisions that made sense under one set of conditions get carried forward because touching them feels riskier than leaving them alone, whether or not the original conditions are still true. Part 3 was about spotting those decisions ahead of time. This one is about what to do once you’ve spotted them.
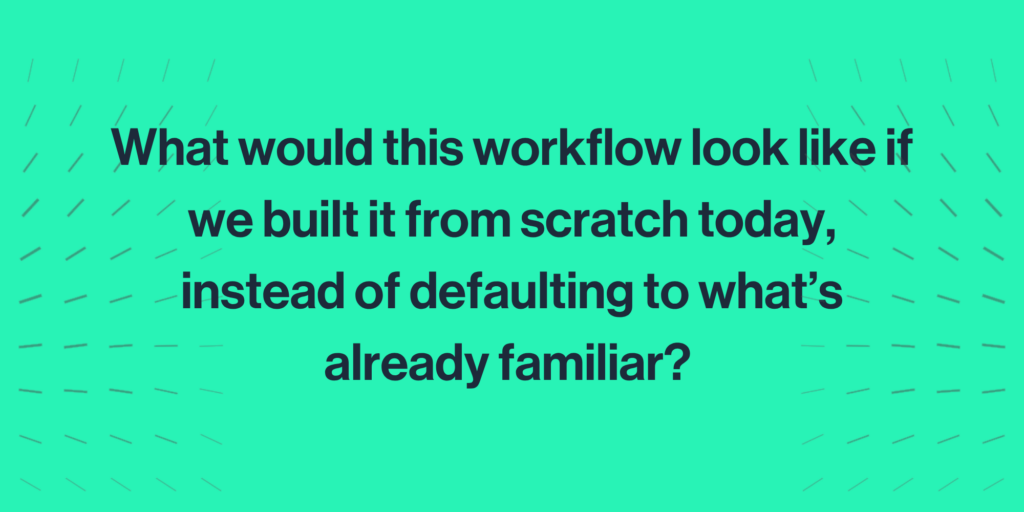
In practice, that means putting one specific question into every design conversation: What would this workflow look like if we built it from scratch today, instead of defaulting to what’s already familiar? If the answer comes out different from what’s actually on the table, that’s the flag, and it costs about 30 seconds to ask. One person in the room willing to ask before the design doc gets written is enough to make it count.
Requirements gathering mostly sets the outer boundary, budget, scope, timeline, and it’s finished before the design conversations that surface what a workflow actually needs. That’s why a smaller technical decision, the same SFTP-versus –API question Part 2 traced back to WEIM, for example, never needs a change order. It’s a normal delivery decision, made and lived with inside design and the stories that follow, and nobody has to write down why one was picked over the other. Swapping a spreadsheet-driven workflow for an actual platform capability is different: Once that surfaces, it usually triggers a change order, because the scope has genuinely changed. Caught during design, it’s an ordinary scope conversation. Caught after stories are already built around the old way, or after go-live, it costs a lot more.
A design decision becomes an implementation story once build starts, which is where optimizing stops being a concept and turns into an actual line in a backlog. Take the same spreadsheet-to-platform swap from above: Writing that story instead of defaulting to the old file-and-reconcile pattern is what walking through the window while it’s still open looks like in practice, a story that could have gone either way and got decided instead of defaulted.
Testing gets treated almost entirely as proving the new build works, which is fair, but it’s also a decent place to test whether the old workaround is still doing anything. Run it side by side with the platform capability that’s supposed to replace it, before the manual step gets baked back into somebody’s routine. Waiting until six months after go-live to ask that question is a lot harder, mostly because by then it’s somebody’s job.
None of this needs a new title or a bigger team, just somebody during design, and in the stories that follow, whose job is to ask the annoying question instead of the efficient one. Often that’s someone who’s already lived through an earlier version of the same implementation and has a decent sense of which shortcuts mattered.
What changes with this approach is who’s making these decisions, and when. A workflow surviving because somebody walked through the window while it was still open is a real result, worth the credit it doesn’t usually get next to one that just survived because nobody argued otherwise.
So here’s the actual ask, if you’re in the middle of one of these implementations right now. Don’t wait for someone five years out to ask why a workflow looks the way it does. Ask this quarter, in the design conversation you’re already having. Put the reason in the story, not just the workflow. Use the testing cycle already on your calendar to check the old pattern against the new one, not just to sign off on the build. None of that needs a new process or a new team, just doing it now, while it’s still cheap, instead of after go-live, when it isn’t.
I can say that with some confidence because I’ve asked these questions from both chairs. On the client side, asking felt like admitting something got missed. On the vendor side, it’s just the job. With Markets+, a lot of you get to ask from either chair right now, and it costs less if you do it before go-live.
If you’re just joining the series, start with Part 1: Why Early Market Decisions Are So Hard to Undo, Part 2: How Proven Decisions Become Technical Debt, and Part 3: How to Audit a Workflow That Isn’t Broken. Together they lay the groundwork for what’s covered here.